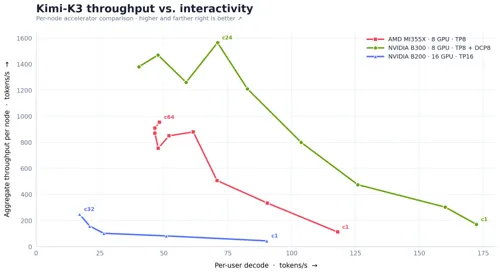
Wafer.ai benchmarked open-source LLM Kimi K3 on AMD MI355X GPUs, finding cost advantages (2.5$/GPU/hr vs NVIDIA B300 at 6$/GPU/hr) but notable performance gaps. ROCm compatibility issues require workarounds (e.g., PyTorch function rewrites, attention head padding), resulting in 118 tokens/s decode rate versus B300's 172 tokens/s. AMD's value proposition is primarily cost-based for price-sensitive AI infrastructure projects.
← Back to all articles