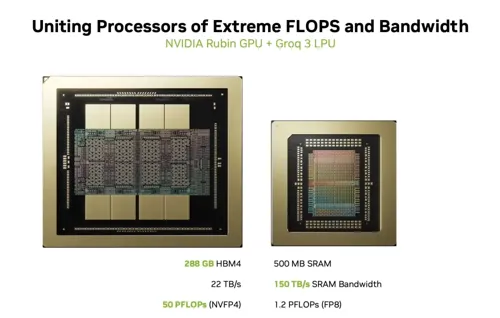
NVIDIA has begun mass production of the Groq 3 LPX chip, positioned as an inference-only extension to its Vera Rubin NVL72 platform. Designed for high-throughput token generation (3,400 tokens/second on Gemma 4 31B), it targets enterprises requiring rapid AI model inference at scale. Early adopter Nebius, a cloud AI compute provider, has already placed orders—relevant for Thai tech companies evaluating AI infrastructure and inference acceleration solutions.
← Back to all articles