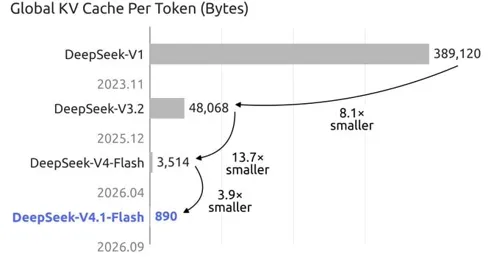
DeepSeek has released V4.1 Flash, a mid-tier LLM that delivers benchmark performance matching GLM-5.3, Kimi K3, and Claude Opus 5, while dramatically reducing operational costs. The model uses an efficient 552B-A8B/A16B architecture with Compressed Sparse Attention 2 and FP4 KV Caching, reducing per-token memory to just 890 bytes (4× more efficient than V4 Flash). Cache pricing is only 1/50 of input pricing, making agentic workflows significantly cheaper. API pricing: $0.3/$1.2 per million tokens (input/output) with cache at $0.006 per million tokens—a major cost advantage for Thai developers and SMEs running AI agents or long-context applications.
← Back to all articles